📝 Batch Normalization
Description
< What is it? >
[Batch normalization (batch norm)]
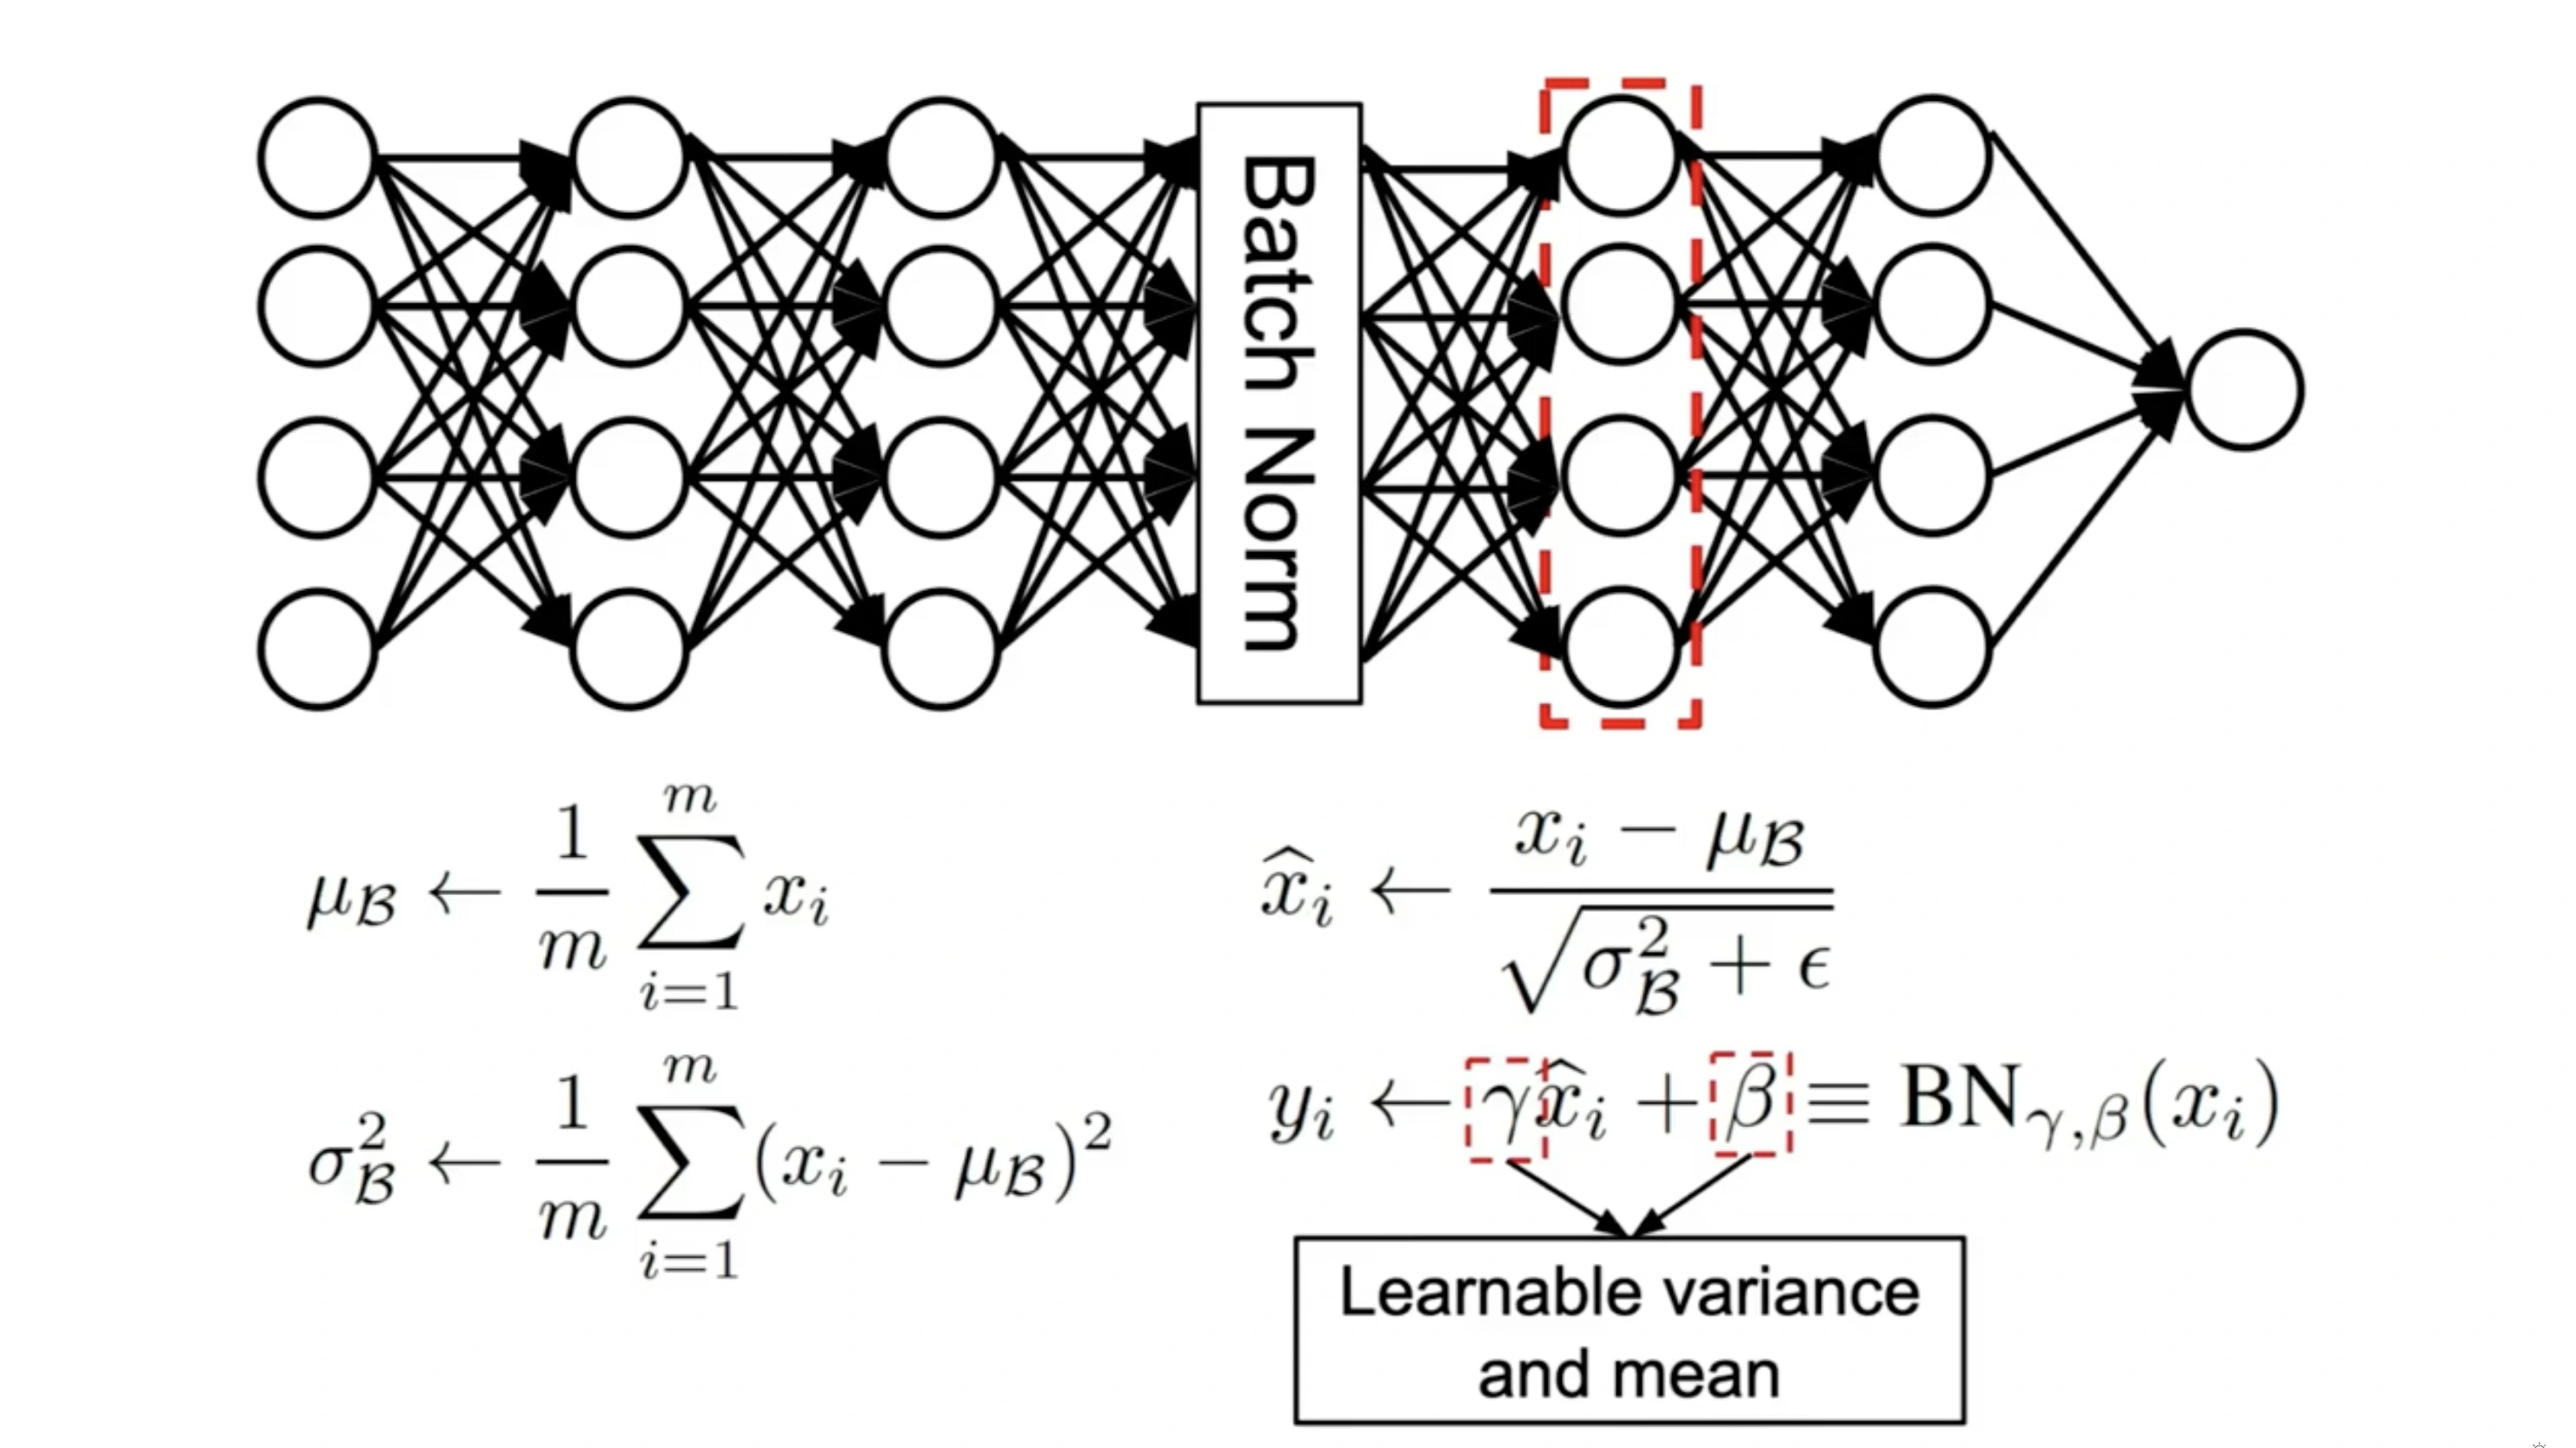
Batch norm normalizes a layer's inputs across the current mini-batch, then rescales the
result with two learnable
parameters. It is a layer, not a preprocessing step: it runs inside the forward pass, every step, on activations
whose distribution keeps shifting as the weights below it change.
For each mini-batch during training, BatchNorm:
- Computes the mean and variance of activations across the batch
- Normalizes them to zero mean, unit variance
- Applies learnable scale (γ) and shift (β) parameters
[Zero mean]
Zero mean means the average value is , not that every value is zero.
For example:
has mean . Subtracting the mean gives:
and:
In BatchNorm, this is done separately for each feature or channel across the mini-batch. It centers that feature's activations around zero before the learned and can rescale and shift them.
[Mini-batch]
A mini-batch is a small, randomly selected subset of the training dataset. Instead of passing the entire dataset through the model at once, we divide it into smaller batches. This allows for more efficient training and helps in stabilizing the learning process.
- Why not the whole dataset (full batch) or one sample (stochastic)?
- Full batch (entire dataset): Slow, memory-heavy, and often gets stuck in sharp local minima.
- Single sample (stochastic, batch size = 1): Fast updates but very noisy, making training unstable.
[Normalization]
Normalization is a technique used to adjust the values of input data to a common scale, without distorting differences in the ranges of values. In the context of batch normalization, it involves scaling and shifting the inputs to have a mean of zero and a standard deviation of one.
< Simple examples >
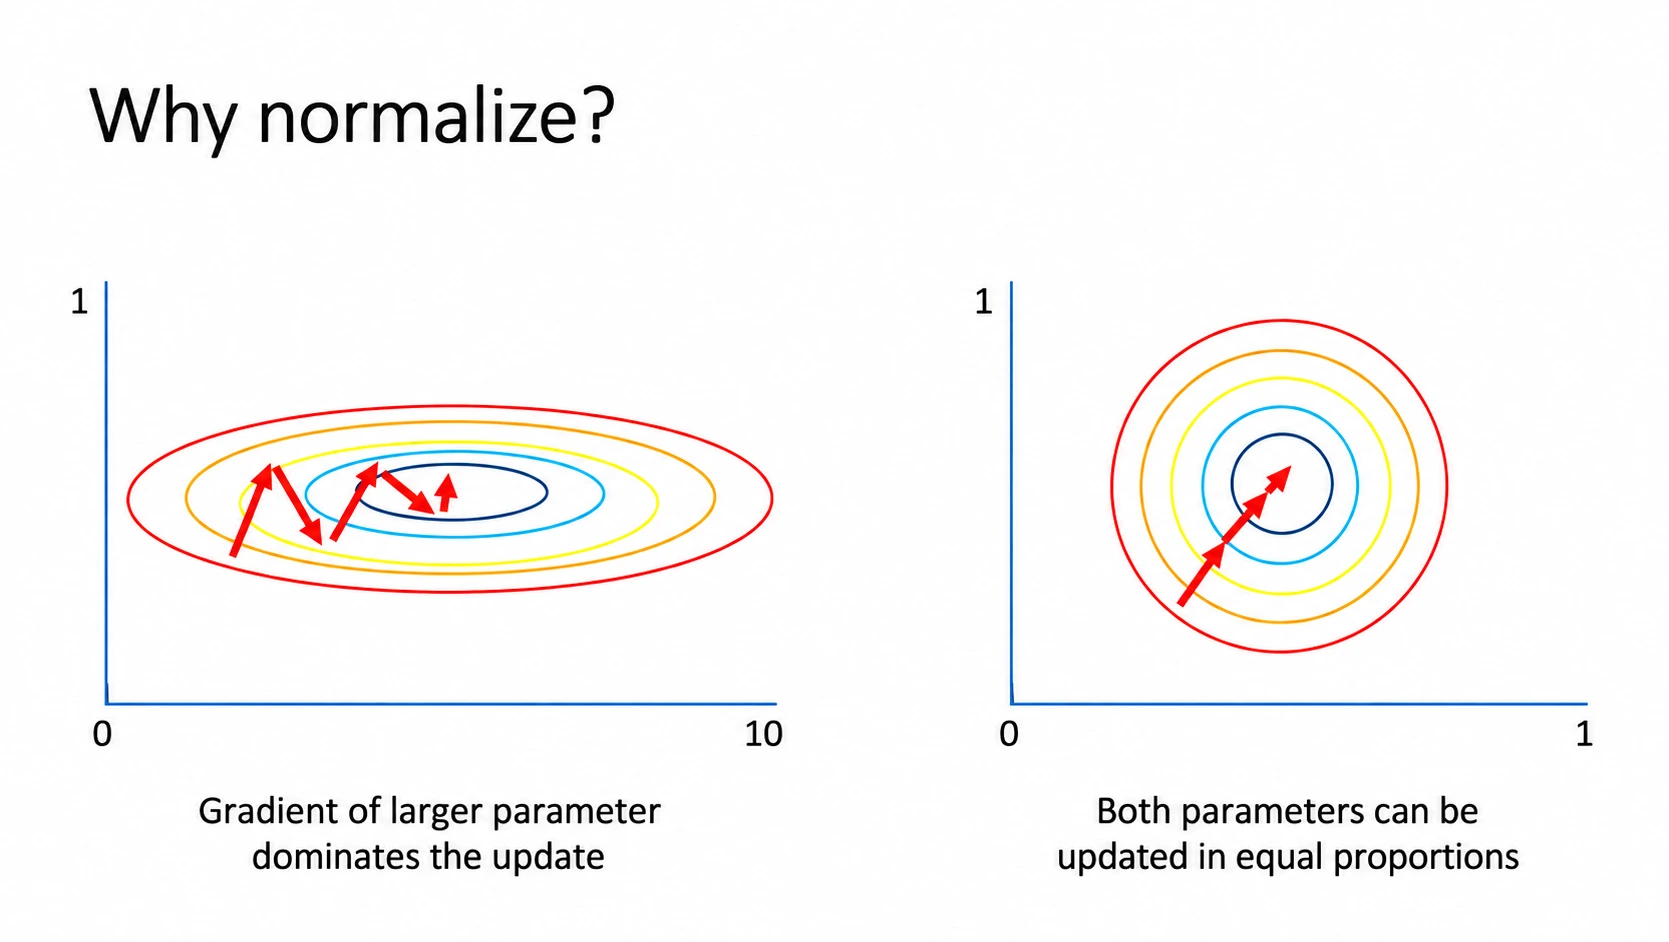
Normalization in general. Imagine a housing model with floor-area values [50, 100, 150] square metres and bedroom counts [1, 2, 3]. The numerical scales differ greatly even though both features may matter. Standardizing either sequence shifts its mean to 0 and scales its standard deviation to 1, producing approximately [-1.22, 0, 1.22]. The model can then learn from the features without large units such as square metres dominating the optimization merely because their numbers are bigger.
Batch norm inside a network. During one training step, suppose a BatchNorm1d feature produces these four activations for the current mini-batch:
Ignoring the tiny for readability, batch norm first produces:
If the layer learns and , its final output becomes:
For images, BatchNorm2d performs the same idea separately for each channel, using values from all images and spatial positions in the mini-batch.
x ──▶ normalize with the batch's μ, σ² ──▶ scale by γ, shift by β ──▶ y
        (zero mean, unit variance)          (learnable, per feature)
Without the second half, forcing every layer to zero mean and unit variance would throw away representational power — a sigmoid unit could never operate anywhere but its linear middle. The learnable and give that power back: the layer can recover any mean and scale it needs, including the identity.
< The computation >
For a mini-batch of examples, computed per feature (per channel, for images):
Reading the symbols
— the subscript just means "over the batch".| Symbol | Name | What it is |
|---|---|---|
| miu | The mean of the feature across the mini-batch | |
| sigma | The variance across the mini-batch. on its own is the standard deviation, which is what the formula's square root recovers | |
| epsilon | A small constant, typically 1e-5, that guards the division when a feature is constant across the batch | |
| gamma | The learned scale, one per feature | |
| beta | The learned shift, one per feature |
and are trained by backpropagation like any other parameter — one pair per
feature, so a BatchNorm2d(64) layer adds 128 trainable values.
Key points
< Why it works >
-
Reduces internal covariate shift (original explanation)
As weights update during training, the distribution of inputs to each layer keeps shifting. BatchNorm re-centers and re-scales these distributions, so each layer sees more consistent input statistics. This lets layers learn without constantly chasing a moving target. -
Smoother optimization landscape(modern explanation)
Later research (Santurkar et al., 2018) showed the main benefit isn't really covariate shift — it's that BatchNorm makes the loss landscape smoother. This:- Allows higher learning rates without divergence
- Reduces sensitivity to initialization
- Makes gradients more predictive, so optimizers take more reliable steps
-
Regularization effect
Because normalization uses batch statistics that vary from batch to batch, it adds noise to the training process. This acts like a mild regularizer, sometimes reducing the need for dropout. -
Gradient flow
By keeping activations in a well-behaved range (especially with sigmoid/tanh), BatchNorm prevents gradients from vanishing or exploding as badly, helping deep networks train.
< Covariate shift, and the "internal" kind >
Covariate shift is a change in the distribution of the input features between the data a model was trained on and the data it later sees. The defining condition is that the rule survives the change:
Train a self-driving model on sunny daytime photographs and deploy it on foggy night streets: a stop sign is still a stop sign, so is the same rule as before — but the pixel distribution is nothing like the training set, and the model has no reason to generalize into that unfamiliar input space. Only moved, and that was enough.
Real product example — booking. A booking model is trained mostly on desktop traffic from returning users. A new
mobile-only campaign then brings many first-time visitors, so the distributions of the device and returning_user
features change: has moved. If two users with the same price, location, trip details, and history still follow
the same booking rule, has not changed. The model can nevertheless perform worse because it saw too few
first-time mobile visitors during training.
Internal covariate shift applies the same idea one layer down. Every layer's input is the previous layer's output, and the previous layer's weights change on every step — so each layer is chasing an input distribution that keeps moving underneath it. The argument is that this slows training, because later layers spend their capacity re-adapting instead of learning.
That was the original motivation for batch normalization: hold each layer's input distribution steady, and the layers above it can stop chasing. Later work (Santurkar et al., 2018) found the explanation does not hold up under measurement — batch norm helps even when noise is deliberately injected to restore the shift — and attributes the benefit instead to a smoother loss landscape with more predictable gradients. The technique works either way; the smoothing account is the better answer in an interview.
The two are worth keeping apart. Internal covariate shift happens during training and batch norm addresses it; ordinary covariate shift happens after deployment and normalization does nothing for it. That one is a data problem — retraining on representative data, or detecting the drift and flagging it. It also breaks calibration, whose guarantees hold only on the distribution the calibrator was fitted to.
< Covariate shift vs. data drift >
Data drift is the broader term: production data differs from the data used for training. Covariate shift is one specific kind of data drift, in which the input population changes but the underlying prediction rule does not.
| Term | What changes | Example |
|---|---|---|
| Covariate shift | while stays the same | A new campaign brings more first-time mobile users, but users with the same features still follow the same booking rule |
| Data drift | Any meaningful production-data change; teams sometimes use the term as a synonym for covariate shift | A feature distribution changes, a category becomes much more common, values become missing, or a feature pipeline changes |
If the relationship between the features and outcome changes — for example, a new pricing policy changes how a given price affects booking — that is concept drift, not merely covariate shift. A broken feature pipeline can also look like drift, but it is an operational problem rather than a population change.
< Training vs. inference — the distinction that bites >
| Mode | Statistics used | Set by |
|---|---|---|
| Training | , of the current batch | model.train() |
| Inference | Running averages accumulated during training | model.eval() |
During training the layer also updates a running mean and variance (an exponential moving average, controlled by
momentum, default 0.1). At inference those fixed running values are used instead, so a prediction depends only on
the input — not on whatever else happened to be batched alongside it.
Forgetting model.eval() is the classic bug: predictions change depending on batch composition, evaluation scores move
between runs, and a batch of size 1 normalizes an example against itself, producing zeros. model.eval() also switches
dropout off, which is why it is a single call for both.
< In PyTorch >
| Layer | Input shape | Normalizes over | Typical use |
|---|---|---|---|
nn.BatchNorm1d(C) | (N, C) or (N, C, L) | N (and L) | Fully connected layers, 1-D signals |
nn.BatchNorm2d(C) | (N, C, H, W) | N, H, W | Images — the common case in CNNs |
nn.BatchNorm3d(C) | (N, C, D, H, W) | N, D, H, W | Volumetric data, video |
import torch.nn as nn

model = nn.Sequential(
    # bias=False: BatchNorm's β makes the preceding bias redundant
    nn.Conv2d(3, 64, kernel_size=3, padding=1, bias=False),
    nn.BatchNorm2d(64),
    nn.ReLU(),
)

model.train()   # batch statistics; running averages updated
model.eval()    # running averages; nothing updated
The argument is the feature/channel count, not the batch size. Two practical notes: the preceding layer's bias is
redundant (β already provides the offset, so use bias=False), and the conventional order is
Linear/Conv → BatchNorm → activation, following the original paper.
< Batch size sensitivity >
Batch norm estimates and from the batch, so the estimates get noisier as the batch shrinks. Below roughly 8–16 examples the noise starts to hurt more than it regularizes; at a batch size of 1 the layer is undefined in training mode. This is the direct link between batch norm and your choice of mini-batch size, and it is why memory-constrained training (large images, detection, segmentation) often switches to a batch-size-independent alternative.
For those cases — and for transformers and RNNs, where sequence examples vary in length — layer norm or RMSNorm normalize within a single example instead. See Normalization inside the network for the comparison.
Related ideas
- Data Normalization scales the inputs before training; batch norm scales activations during it. Doing one does not remove the need for the other.
- Vanishing & Exploding Gradients covers what batch norm can and cannot fix.
- Regularization puts its noise-based side effect in context.
- Calibration is one of the first things ordinary covariate shift breaks after deployment.
Video Tutorial
- Batch Norm vs Layer Norm - Explained
- Why Batch Normalization Works
- Why Does Batch Norm Work? (C2W3L06)
Reference
- Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift — Ioffe & Szegedy (2015)
- How Does Batch Normalization Help Optimization? — Santurkar et al. (2018)
- PyTorch
nn.BatchNorm2ddocumentation - Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift (Ioffe & Szegedy, 2015)
- How Does Batch Normalization Help Optimization?
- Normalizing your data (specifically, input and batch normalization)