📝 Gradient Descent
Description
< What is it? >
- [The idea]
-
Gradient descent is the iterative optimizer behind almost all model training: start from random parameters, measure which direction increases the loss, and step the other way. Repeat until the loss stops improving (convergence).
-
The gradient
∇J(θ)(∇: Nabla = differential operator, here is the gradient) is the vector of partial derivatives of the loss with respect to every parameter. It points in the direction of steepest increase, so−∇J(θ)is the steepest descent direction — hence the minus sign:θ := θ − α · ∇J(θ)│ │ │new │ gradient of the loss w.r.t. every parameterparams learning rate α (step size) -
Nothing about this is specific to neural networks. It is the same rule for linear regression, logistic regression and a 100-billion-parameter transformer — only the way the gradient is computed differs (a closed-form expression for the simple cases, backpropagation for deep nets).
-
- [What it requires]
- A loss that is differentiable with respect to the parameters. This is why classification models optimize cross-entropy rather than accuracy: accuracy is a step function with zero gradient almost everywhere.
- Models whose parameters are not fit by a continuous objective — decision trees and their ensembles — do not use it. They search over discrete splits instead.
- [The training loop]
repeat until converged:1. forward — compute predictions ŷ for a batch of examples2. loss — compare ŷ to y, get a single scalar J3. backward — backpropagate to get ∇J(θ) for every parameter4. step — θ := θ − α · ∇J(θ)
< Training-loop terminology >
| Term | Meaning |
|---|---|
| Batch | A group of training examples processed together in one forward and backward pass |
| Mini-batch | A small batch—usually only part of the training set—used for one step. In practice, “batch” usually means “mini-batch” |
| Iteration / step | One parameter update using one batch |
| Epoch | One complete pass through all training batches |
< Example >
For example, suppose you have 1,000 training examples:
- Batch size = 100
- Each batch causes one parameter update
- Number of updates per epoch:
Therefore:
- 1 epoch = process all 1,000 examples once = 10 updates
- 5 epochs = process them five times = 50 updates
- 100 epochs = process them 100 times = 1,000 updates
< Batch, stochastic, mini-batch >
| Variant | Examples per step | Gradient quality | Reality |
|---|---|---|---|
| Batch (full) | All m | Exact, smooth descent | One update per epoch. Too slow, and the dataset may not fit in memory |
| Stochastic (SGD) | 1 | Very noisy | Updates constantly, but loses cross-example vectorization and often underuses hardware |
| Mini-batch | 32 – 8192 | Noisy but usable | What everyone actually uses. Vectorizes across examples, and the noise is useful |
< Why use an intermediate mini-batch size? >
Let be the total number of training examples. A useful mini-batch size is often neither nor :
- With a mini-batch size of , computation loses vectorization across examples, so hardware is often used less efficiently.
- With a mini-batch size of , parameters are updated after each example; training does not wait for the entire training set before making progress.
- With a mini-batch size of , training becomes batch gradient descent and must process the whole training set before each parameter update.
- With a mini-batch size of , training is batch gradient descent, not stochastic gradient descent. One full-batch iteration is usually slower than one mini-batch iteration, although an epoch is not necessarily faster because both process all examples.
Practical notes:
- The noise in mini-batch gradients is not purely a cost. It helps the optimizer escape saddle points and narrow minima, which is one reason a moderate batch size often generalizes better than an enormous one.
- Batch size and learning rate are coupled: multiplying the batch size by k roughly permits multiplying the learning rate by k (the linear scaling rule), because each gradient estimate is proportionally less noisy.
- Shuffle every epoch. Data that arrives sorted by label makes each batch's gradient point somewhere unrepresentative.
- Where to start: 32, 64, 128 or 256. The upper end of the table is reserved for large-scale distributed runs; the practical ceiling on a single device is GPU memory, since activations for the whole batch must be held for the backward pass.
- Too small has its own failure mode. Batch normalization estimates its statistics from the batch, so below roughly 8–16 examples those estimates get noisy enough to hurt, and a batch size of 1 leaves it undefined in training mode.
< Activation notation in mini-batch training >
To denote the activation of the 7th example from the 3rd mini-batch at the 4th layer, use:
- identifies the layer
- identifies the mini-batch
- identifies the example within that mini-batch
< Vectorization across examples >
Vectorization across examples means computing a layer for every example in a mini-batch with one matrix or tensor operation, rather than looping over examples in Python.
In the column-vector convention, a mini-batch of examples stores the previous layer's activations as columns:
The next layer then computes all examples at once:
The bias is broadcast to every column. The result is mathematically the same as processing each example separately, but uses fast parallel matrix operations on CPUs and GPUs. Frameworks often store batches with the batch dimension first, such as [B, features], but the idea is the same.
Training still loops over mini-batches. It cannot process every mini-batch at once, because each parameter update changes the parameters used by the next mini-batch.
< The learning rate — the one knob that matters most >
α too small           α about right          α too large
      ╲                     ╲                      ╲    ╱
       ╲....                 ╲                      ╲  ╱ ↑ diverges
        ╲....•                ╲___•                  ╲╱
   creeps, may never    lands in the basin      overshoots the valley,
   reach the minimum    in few steps            loss → NaN
< Learning-rate decay >
Learning-rate decay is a schedule that gradually lowers the learning rate during training. Larger steps early in training make rapid progress; smaller steps later help the optimizer settle into a good solution instead of continually overshooting it.
A common step-decay schedule is:
Here, is the training step, is the decay interval, and shrinks the learning rate at each interval. Other common schedules include cosine annealing and inverse-time decay such as .
- Learning-rate decay is not weight decay. Learning-rate decay changes the size of each optimization step; weight decay discourages large parameter values.
- Warmup does the opposite at the start: it ramps up from near zero over the first few hundred or thousand steps. This can prevent an unstable first update, especially with adaptive optimizers.
- Find a starting value by sweeping on a log scale (
1e-5 … 1e-1) for a few hundred steps and taking the largest value whose loss still falls smoothly.
Key points
< Optimizers: what each one fixes >
| Optimizer | Adds | Fixes |
|---|---|---|
| SGD | — | Baseline. Slow through ravines, sensitive to α |
| + Momentum | Velocity: an exponentially-weighted average of past gradients | Damps zig-zag across a narrow valley, accelerates along it |
| + Nesterov | Look-ahead gradient | Slightly better-damped momentum |
| AdaGrad | Per-parameter α scaled by accumulated squared gradients | Rare features get larger steps — but α decays to zero and training stalls |
| RMSProp | Same, with a moving average instead of a sum | Removes AdaGrad's terminal stall |
| Adam | RMSProp + momentum + bias correction | The robust default. Works well with little tuning |
| AdamW | Decouples weight decay from the adaptive step | Makes regularization behave correctly — see Regularization |
< Exponentially weighted averages >
An exponentially weighted average is a running average that gives more weight to recent values and progressively less weight to older ones:
Here, is the newest value and is usually close to . A value from steps ago has weight , so its influence shrinks by the same factor at every step. For , the newest value has weight , the previous one has weight , then , and so on.
- Large (such as or ): past values receive most of the weight. The average is smoother and less noisy, but responds more slowly to a new value. Its effective history is roughly steps.
- Small (such as or ): the newest value receives more weight. The average responds quickly, but is less smooth and more sensitive to noise.
Momentum applies this idea to gradients. RMSProp applies it to squared gradients, and Adam uses both forms.
-
Example: temperature smoothing and bias correction
Suppose the observed temperature in Casablanca is on March 1 and on March 2. Here, is the thermometer reading on day —not a model parameter—and is the running, smoothed temperature estimate.
Use and :
The first two estimates are:
Because , early estimates are biased toward zero. Bias correction compensates for that initialization:
Therefore:
The corrected estimate weights day 2 twice as much as day 1:
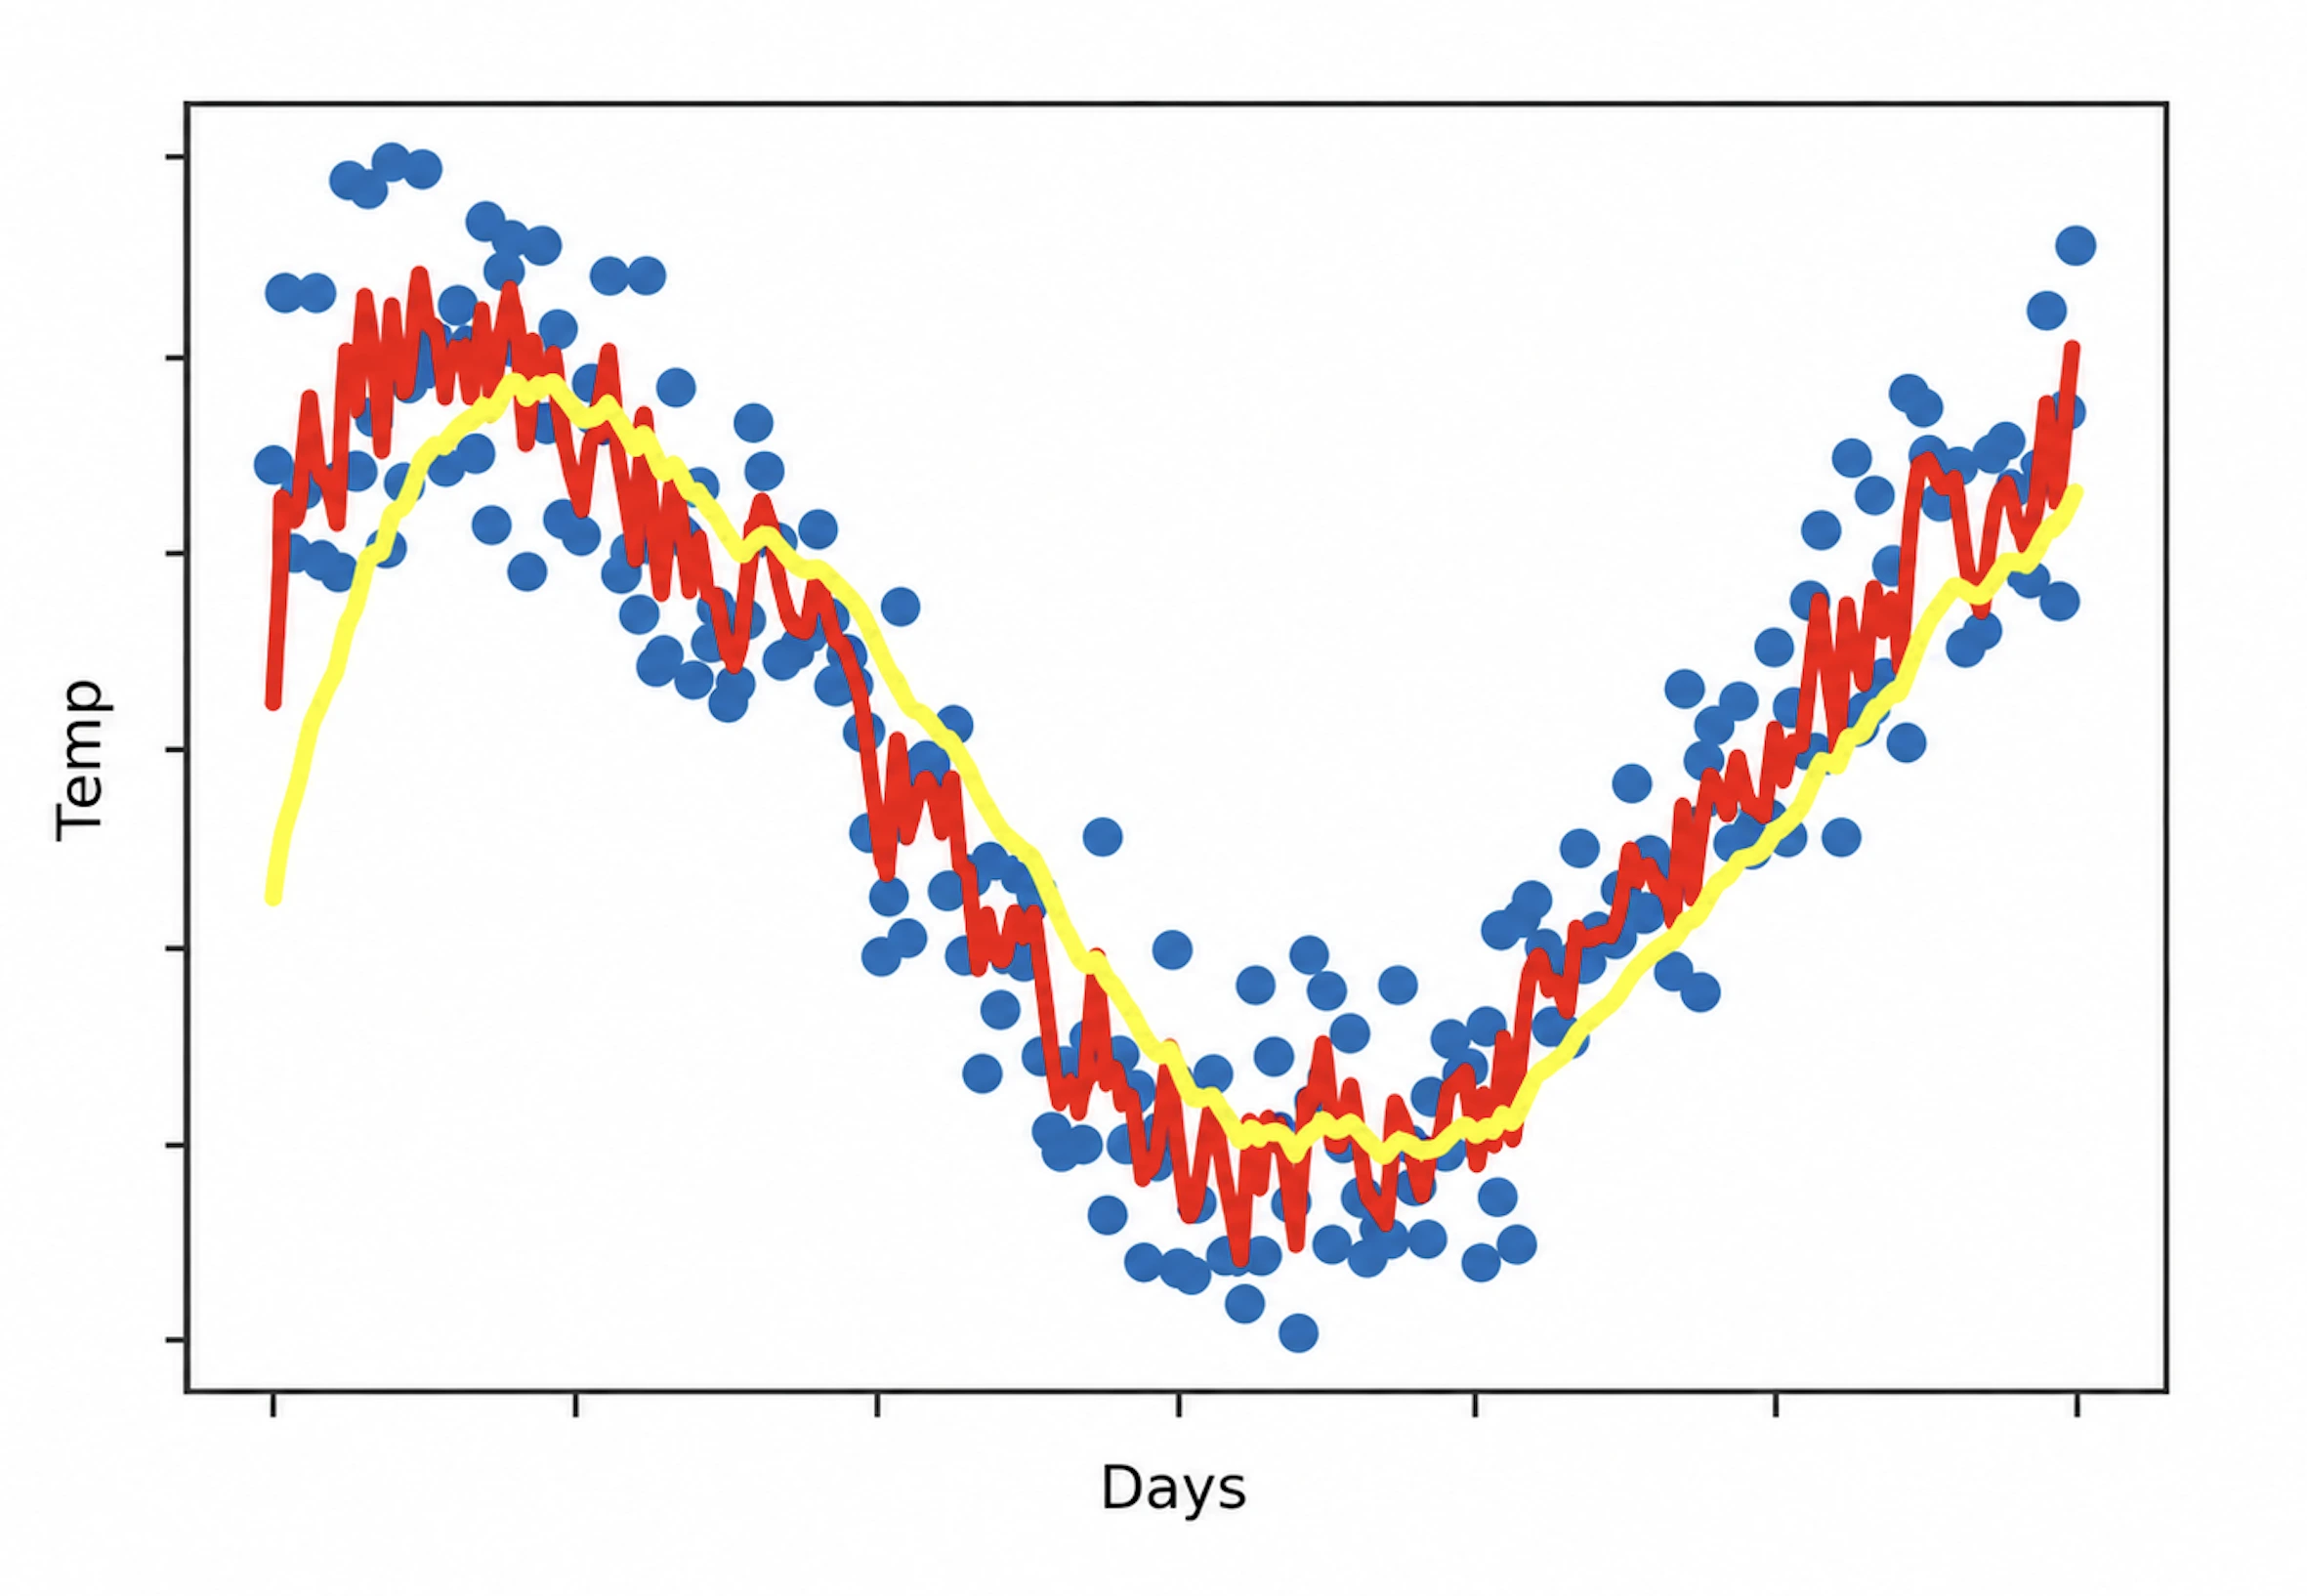
yellow line's beta > red line's beta: red curve is noisier
< Momentum >
Gradient descent with momentum combines the current gradient with an exponentially decaying accumulation of past gradients, often called a velocity:
Here, controls how much past gradients matter and is often set near . When gradients keep pointing in the same direction, momentum accelerates progress. When noisy mini-batch gradients alternate sideways, it smooths those oscillations. Some libraries omit and absorb that scale into ; the underlying idea is the same.
- Momentum is not learning-rate decay. Increasing makes the moving average smoother; it does not automatically reduce the learning rate over epochs. Use a separate learning-rate decay schedule when should decrease during training.
- In practice: AdamW for transformers and most NLP; SGD with momentum still matches or beats it on vision CNNs and often generalizes slightly better; plain SGD for convex problems where you can tune α properly.
- All of them are still gradient descent. They only reshape how the raw gradient is turned into a step.
< The landscape: why this works at all >
- For convex losses (linear regression's MSE, logistic regression's log-loss) there is a single minimum and gradient descent provably finds it. Everything is well behaved.
- Deep networks are non-convex — a surface with countless critical points. The classical worry was getting trapped in a bad local minimum. In high dimensions that turns out to be rare: a local minimum requires every one of millions of directions to curve upward. What you actually hit are saddle points (up in some directions, down in others), and gradient noise plus momentum escape them.
- Most minima found in practice reach a similar loss. Flat minima — wide basins where nearby parameters give similar loss — tend to generalize better than sharp ones, which is another argument for the noise in mini-batch SGD.
< Reading the loss curve >
| Symptom | Likely cause | Move |
|---|---|---|
| Loss → NaN / inf after a few steps | α too large, or exploding gradients | Cut α 10×, add gradient clipping, add warmup |
| Loss flat from step 0 | α far too small, dead ReLUs, or the gradient never reaches the params | Raise α; check requires_grad, zero_grad(), and that the loss is connected to the graph |
| Loss falls then plateaus high | Underfitting, or α now too large to settle | Add capacity, or decay α — see Bias & Variance |
| Very spiky loss | Batch too small, α too large, or unshuffled data | Larger batch, lower α, shuffle |
| Training loss falls, validation rises | Overfitting — not an optimizer problem | Early stopping, regularization |
| Slow zig-zag progress | Ill-conditioned surface from unscaled features | Normalize the inputs; use momentum or Adam |
< Things that quietly break it >
- [Unscaled features] elongated loss contours cap α at whatever the steepest direction tolerates — the geometry argument in Data Normalization.
- [Exploding / vanishing gradients] deep stacks multiply gradients through many layers. Fixes are structural: gradient clipping, residual connections, careful initialization (He/Xavier([ˈzævɪr])), and normalization layers.
- [Forgetting to reset gradients] PyTorch accumulates into
.grad; withoutoptimizer.zero_grad()every step uses the sum of all previous gradients. - [Loss scale under mixed precision] fp16 gradients underflow to zero. Use a gradient scaler, or bf16.
- [Tuning α against the test set] the learning rate is a hyperparameter like any other — see the validation-set rule in Bias & Variance.
< When not to use it >
- Closed form exists. OLS linear regression has the normal equation
θ = (XᵀX)⁻¹Xᵀy— exact, no α to tune. Gradient descent wins once n is large enough that invertingXᵀXis expensive. - Second-order methods (Newton, L-BFGS) use curvature and converge in far fewer iterations, but need the Hessian or an approximation of it — quadratic in the parameter count. Practical for small convex problems, hopeless at deep-learning scale, which is why first-order methods dominate.
Implementation
< Linear Regression Using Gradient Descent >
Question: Write a Python function that performs linear regression using gradient descent. The function should take NumPy arrays X (features with a column of ones for the intercept) and y (target) as input, along with the learning rate alpha and the number of iterations. Return the learned coefficients (weights) as a NumPy array.
Requirements:
- Minimize the Mean Squared Error (MSE) loss function: Here, is the prediction for training example , and is the number of training examples. The factor simplifies the gradient calculation.
- Initialize all weights to zero
- Use batch gradient descent (use all samples in each iteration)
The input matrix X has shape (m, n) where m is the number of training examples and n is the number of features (including the bias column of ones). The target vector y has shape (m,).
Input: X = np.array([[1, 1], [1, 2], [1, 3]]), y = np.array([3, 5, 7]), alpha = 0.1, iterations = 1000
Output: [1.0, 2.0]
Solution:
The vectorized loss is
so its gradient is
Step-by-step derivation of the gradient
Let the prediction error vector be
The squared norm is the sum of squared errors:
Therefore,
Derivation by expansion
Expand the product:
Differentiate each term with respect to :
because is symmetric, and
The final term does not depend on :
Putting everything together:
The factor in the loss cancels the produced when differentiating the squared error.
Element-by-element interpretation
For parameter ,
This means:
- Compute every prediction error, .
- Multiply each error by its corresponding feature value.
- Sum across all training examples using .
- Divide by .
Stacking all parameter derivatives into one vector gives
The gradient-descent update is consequently
import numpy as np

def linear_regression_gradient_descent(X: np.ndarray, y: np.ndarray, alpha: float, iterations: int) -> np.ndarray:
"""
Perform linear regression using gradient descent.

Args:
    X: Feature matrix of shape (m, n) where first column is all ones (for intercept)
    y: Target vector of shape (m,)
    alpha: Learning rate
    iterations: Number of gradient descent iterations

Returns:
    Learned weights as a 1D array of shape (n,)
"""
m, n = X.shape
y = y.reshape(-1, 1) # Ensure y is a column vector
theta = np.zeros((n, 1)) # Initialize weights to zeros

for _ in range(iterations):
  predictions = X @ theta
  errors = predictions - y
  gradient = (X.T @ errors) / m
  theta = theta - alpha * gradient
return theta.flatten()
Q&A
< What is convergence? >
- Convergence is when the loss stops improving. In practice, this is usually defined as a plateau in the validation loss, or a small enough gradient norm. It does not necessarily mean that the model has reached the global minimum of the loss function, especially in non-convex problems like deep learning.
< Is convergence to the global optimum guaranteed? >
-
Not always.
For convex loss functions, gradient descent is guaranteed to converge to the global optimum.
However, for non-convex loss functions, such as those encountered in deep learning, convergence to a global optimum is not guaranteed. Instead, the algorithm may converge to a local minimum or saddle point. -
Convex Objectives
If is convex and differentiable, every local minimum is global. Gradient descent converges to a global optimum under standard conditions, such as:
- The gradient is Lipschitz-continuous.
- The learning rate is sufficiently small, often , where is the gradient smoothness constant.
- An optimum exists.
For a smooth convex function, the typical objective-gap rate is:
If the function is also strongly convex, convergence is geometric:
-
Non-Convex Objectives
For non-convex objectives, including most neural networks, global optimality is not generally guaranteed. Gradient descent can encounter:
- Multiple local minima

- Saddle points

- Flat plateaus

- Poorly conditioned regions
- Vanishing or exploding gradients
Under smoothness assumptions, a common guarantee is only convergence toward a stationary point:
A stationary point can be a local minimum, local maximum, or saddle point—not necessarily a global optimum.
- Multiple local minima
-
Stochastic Gradient Descent
Stochastic gradient descent (SGD) uses a noisy gradient estimate from a sample or mini-batch:
Its noise makes updates cheaper and can help escape some saddle points or shallow local minima. However, with a fixed learning rate, SGD often fluctuates around a solution rather than converging exactly. Suitable decreasing learning rates, such as conditions
can provide convergence guarantees under additional assumptions.
-
Practical Takeaway
Convex problem:
Global convergence is often guaranteed with an appropriate learning-rate schedule.Strongly convex problem:
Global convergence is usually fast and the optimum is unique.Non-convex problem:
Usually only stationary-point convergence is guaranteed.Deep learning:
There is generally no global-optimum guarantee, although overparameterization, initialization, normalization, adaptive optimizers, and SGD often produce good solutions empirically.
Video Tutorial
- Gradient descent
- (Vanilla) Gradient Descent
- STOCHASTIC Gradient Descent
- MOMENTUM Gradient Descent
Reference
- An overview of gradient descent optimization algorithms (Sebastian Ruder)
- Why Momentum Really Works (Distill)